

Linux Foundation CKAD Cert Guide PDF 100% Cover Real Exam Questions
Pass CKAD Exam - Real Questions and Answers
The CKAD certification exam is a performance-based exam that tests the candidate's ability to design, build, and deploy Kubernetes-based applications. CKAD exam is conducted online and consists of a set of performance-based tasks that require the candidate to perform real-world tasks using a Kubernetes cluster. The candidate is required to demonstrate their ability to use Kubernetes to deploy and manage containerized applications, configure Kubernetes objects, and troubleshoot common issues.
NEW QUESTION # 78
You have a Deployment named 'web-app-deployments that runs a web application in a containerized environment. The application is designed for high availability and scalability, but you need to ensure that no more than two pods are ever terminated simultaneously during a rolling update process. This is to minimize the impact on service availability during the update. How would you implement this rolling update strategy using Deployment resources?
Answer:
Explanation:
See the solution below with Step by Step Explanation.
Explanation:
Solution (Step by Step) :
I). Update the Deployment YAML:
- Modify the 'strategy.roIIinglJpdate' section of the Deployment YAML to configure the rolling update behavior.
- Set 'maxunavailable: 1 ' to allow only one pod to be unavailable at a time during the update.
- Set 'maxSurge: 1 ' to permit only one additional pod to be created beyond the desired replica count during the update.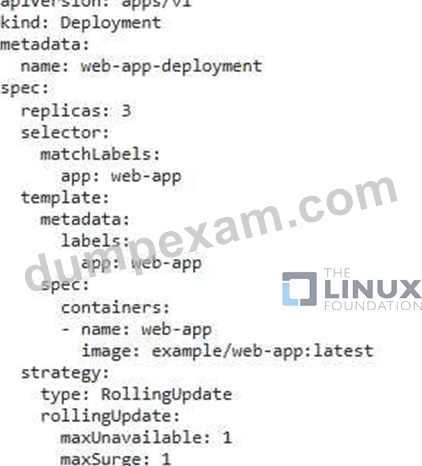
2. Apply the Updated Deployment: - Use ' kubectl apply -f web-app-deployment-yamr to update the Deployment. 3. Monitor the Rolling Update: - Observe the pod updates using 'kubectl get pods -I app=web-app' - You will see that during the rolling update, only one pod is terminated, while one new pod is created, ensuring that no more than two pods are ever terminated at the same time. 4. Verify the Update: - Once the rolling update is complete, check the 'updatedReplicaS field in the Deployment description Ckubectl describe deployment web-app- deployment) to verify that it matches the 'replicas' field.
NEW QUESTION # 79
You have a Deployment named 'wordpress-deployment' that runs 3 replicas of a WordPress container. You need to implement a persistent volume claim (PVC) for each pod that stores the website data, and you want to ensure that the data persists even if the pod is deleted or restarted. The PVC should be created using a storage class named 'standard' with a capacity of 10Gi.
Answer:
Explanation:
See the solution below with Step by Step Explanation.
Explanation:
Solution (Step by Step) :
I). Create a Storage Class:
- Create a 'standard' storage class: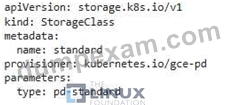
- Apply the YAML file: bash kubectl apply -f standard-storage-class-yaml 2. Create a Persistent Volume Claim: - Create a PVC named 'wordpress-pvc' with a request for IOGi storage and using the 'standard' storage class: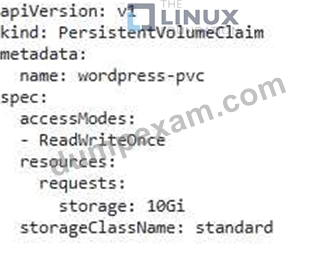
- Apply the YAML file: bash kubectl apply -f wordpress-pvc.yaml 3. Update the Deployment - Update the Swordpress-deployment' YAML file to mount the PVC to each pod: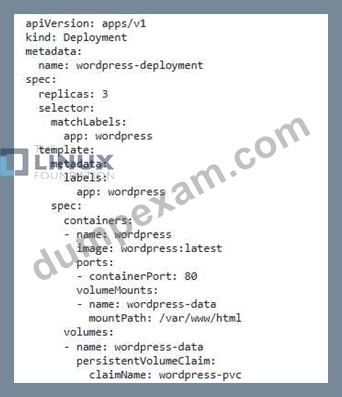
- Apply the updated YAML file: bash kubectl apply -f wordpress-deployment_yaml 4. Verify the Deployment - Check the status of the deployment using 'kubectl get deployments wordpress-deployment' to confirm the rollout and updated replica count. - Use 'kubectl describe pods -l app=wordpress' to confirm that each pod is using the 'wordpress-pvc' and the website data is stored in the persistent volume. - You can now access the WordPress website through the service that is associated with the Deployment. 5. Test Data Persistence: - Delete or restan one of the pods in the deployment. - Observe that the website data remains intact because the PVC is persistent and the data is stored in the underlying volume.,
NEW QUESTION # 80
You have a Deployment running a web application that is scaling dynamically based on traffic. However, the application occasionally experiences Slow response times during peak traffic periods. You suspect that the pods are being scheduled on nodes that are already under pressure. To improve the performance, you want to implement node affinity, ensuring that pods are scheduled on nodes with specific labels that indicate high resources and low utilization.
Answer:
Explanation:
See the solution below with Step by Step Explanation.
Explanation:
Solution (Step by Step) :
1. Define Node Labels:
- Identify nodes with high resources and low utilization.
- Label these nodes with a specific label like 'high-resource':
bash
kubectl label nodes node-name high-resource=true
2. Configure Node Affinity in Deployment
- Update tne Deployment YAML to include node affinity rules.
- preferredDuringSchedulinglgnoredDuringExecution: This affinity rule indicates a preference for scheduling pods on nodes with specific labels. It doesn't prevent scheduling on other nodes if preferred nodes are unavailable.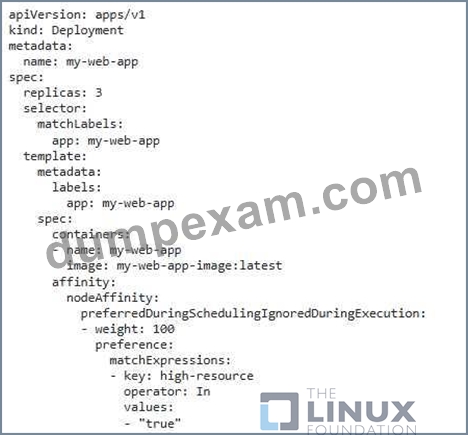
3. Apply the Deployment Configuration: - Apply the updated Deployment configuration to your Kubernetes cluster: bash kubectl apply -f my-web-app-deployment.yaml 4. Monitor Pod Scheduling: - Use 'kubectl get pods -l app=my-web-app' to monitor the pod scheduling. - Verity that the pods are being scheduled on nodes with the 'high-resource' label.
NEW QUESTION # 81
You are deploying a microservice application that requires secure access to an external database. The database credentials are stored as environment variables Within the application container. You want to create a Kubernetes secret that securely stores these credentials and can be mounted as a file in the container.
Answer:
Explanation:
See the solution below with Step by Step Explanation.
Explanation:
Solution (Step by Step) :
1. Create a Kubernetes Secret:
- Create a YAML file, for example, 'database-secret.yamr , with the following content: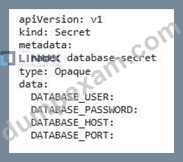
- Replace ". ". ". and with the actual values, Base64 encoded. You can use the 'base64' command to encode the values: bash echo "your _ username" | base64 echo 'Your_password" | base64 echo "your _ host" | base64 echo "your _ port" | base64 2. Apply the Secret: - Apply the secret to your Kubernetes cluster: bash kubectl apply -f database-secret.yaml 3. Modify the Deployment: - Modify your Deployment YAML file to mount the secret as a file: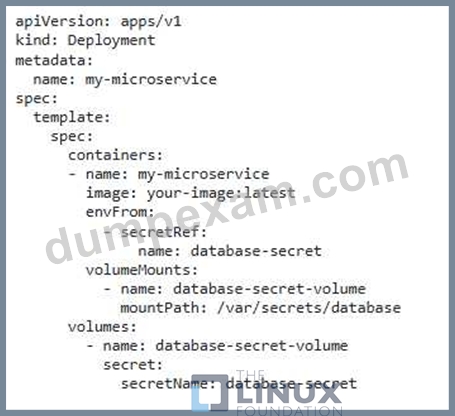
4. Apply the Updated Deployment: - Apply the updated Deployment YAML file using: bash kubectl apply -f my-microservice-deployment.yaml 5. Accessing Credentials: - The application container can now access the environment variables from the secret using 'process-env-DATABASE USER , 'process.env.DATABASE_PASSWORD', etc. Additionally, the secret data is mounted as a file at '/var/secrets/database'.
NEW QUESTION # 82
You are tasked witn building a container image for a Node.js application that needs to interact with a MongoDB database. Describe now you would configure your Dockerfile to include MongoDB and how you would set up your Node.js application to connect to the database within the container.
Answer:
Explanation:
See the solution below with Step by Step Explanation.
Explanation:
Solution (Step by Step) :
1. Utilize a Multi-Stage Dockerfile: Employ a multi-stage Dockerfile to separate the build and runtime environments, optimizing the final image size.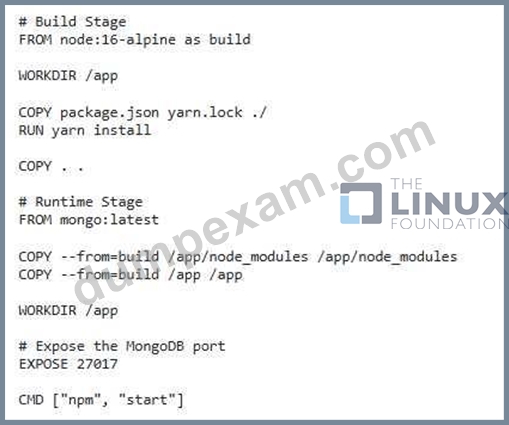
2. Install MongoDB in the Base Image: - Use a suitable MongoDB base image, such as 'mongo:latest', in the runtime stage. 3. Install Node.js Dependencies: - IJse a Nodejs base image, such as 'node:16-alpine', in the build stage. - Install Node.js dependencies using 'yarn install'. 4. Connect to MongoDB from the Node.js Application: - In your Node.js application, use a MongoDB driver (e.g., 'mongodb') to establish a connection to the MongoDB instance.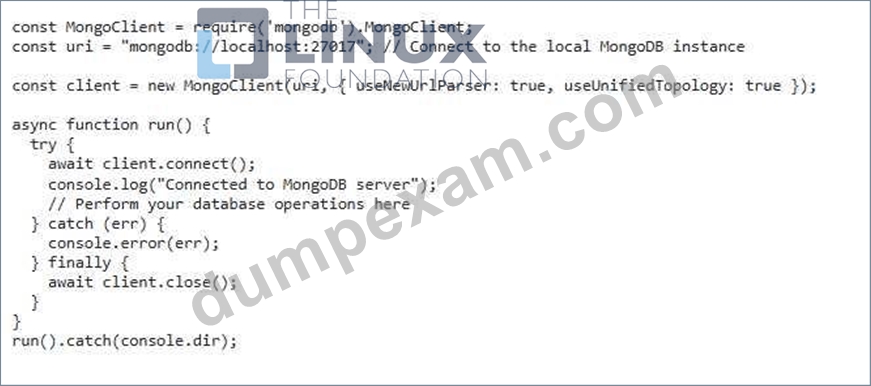
5. Build and Run the Container: - Build the image using 'docker build . -t my-node-mongo-apps - Run the container using 'docker run -it -p 2701727017 my-node-mongo-app' - The '-p 27017:27017' mapping exposes the MongoDB port to your host machine, allowing you to connect to the database from your local machine. 6. Access MongoDB. - You can use a MongoDB client tool (e.g., Mongo Shell, Robo 3T) or other applications to connect to the MongoDB instance running inside the container.,
NEW QUESTION # 83
You must connect to the correct host . Failure to do so may result in a zero score.
[candidate@base] $ ssh ckad00034c
Task
A Deployment named content-marlin-deployment , running in namespace content-marlin is exposed via Ingress content-marlin-ingress .
The manifest files for the Deployment, Service and Ingress can be found at /home/candidate/content-marlin/.
The Deployment is supposed to be reachable at
http://content-marlin.local/content-marlin , but requesting this URL is currently returning an error.
Answer:
Explanation:
See the Explanation below for complete solution.
Explanation:
ssh ckad00034c
You're debugging an Ingress # Service # Deployment chain. The fastest way is:
* reproduce the error with the right Host header
* check Ingress rules (host/path/backend)
* check Service (selector/port/targetPort)
* check Endpoints (do we have ready pods?)
* fix the manifest(s) under /home/candidate/content-marlin/
* apply + re-test
Below are the exact commands + the most common fixes for this exact symptom.
1) Reproduce the failing request correctly
Even if DNS isn't set up, you can test with a Host header:
curl -i -H "Host: content-marlin.local"
http://127.0.0.1/content-marlin
If your ingress controller is not on localhost, find the NodePort/LoadBalancer IP. In these labs it's often localhost via a local proxy, but if needed:
kubectl get svc -A | egrep -i 'ingress|nginx'
kubectl get nodes -o wide
(But start with the localhost curl above.)
2) Inspect the provided manifests (this is what you must edit)
cd /home/candidate/content-marlin/
ls -l
sed -n '1,200p' *.yaml
Also view what's currently live in the cluster:
kubectl -n content-marlin get deploy,svc,ingress
kubectl -n content-marlin describe ingress content-marlin-ingress
kubectl -n content-marlin get ingress content-marlin-ingress -o yaml
What to look for in the Ingress:
* spec.rules.host should be content-marlin.local
* spec.rules.http.paths[].path should match /content-marlin
* Backend service name must be your service
* Backend service port must match the service port (name or number)
* pathType should be Prefix (usually safest)
3) Validate Service # Pod wiring (most common real cause)
3.1 Check service selector and ports
kubectl -n content-marlin get svc -o wide
kubectl -n content-marlin describe svc content-marlin-deployment 2>/dev/null || true kubectl -n content-marlin describe svc Identify the service that the Ingress points to (from describe ingress).
Check if the Service selector matches pod labels:
kubectl -n content-marlin get pods --show-labels
kubectl -n content-marlin get svc <SERVICE_NAME> -o jsonpath='{.spec.selector}{"\n"}'
3.2 Check endpoints (this tells you instantly if traffic can reach pods) kubectl -n content-marlin get endpoints kubectl -n content-marlin get endpoints <SERVICE_NAME> -o wide
* If ENDPOINTS is empty # Service selector doesn't match Pods OR Pods aren't Ready.
3.3 If endpoints empty, check pod readiness and labels
kubectl -n content-marlin get pods -o wide
kubectl -n content-marlin describe pod <pod-name>
4) Apply the most likely fix patterns
Fix pattern A: Ingress path needs rewrite
If your app serves / but you route /content-marlin, you often need rewrite.
Edit content-marlin-ingress manifest (in /home/candidate/content-marlin/) to include:
* path: /content-marlin
* pathType: Prefix
* annotation: rewrite to / (common for nginx ingress)
Example (typical nginx-ingress):
metadata:
annotations:
nginx.ingress.kubernetes.io/rewrite-target: /
spec:
rules:
- host: content-marlin.local
http:
paths:
- path: /content-marlin
pathType: Prefix
backend:
service:
name: <SERVICE_NAME>
port:
number: 80
If your ingress controller is not nginx, rewrite annotation may differ. But in CKAD labs, it's very often nginx.
Fix pattern B: Ingress points to wrong Service port
If the Ingress backend says port 80 but your Service exposes 8080 (or uses a named port), align them:
* Either change Ingress backend port.number
* Or change Service spec.ports[].port / targetPort
Fix pattern C: Service selector mismatch (endpoints empty)
If pods have label app=content-marlin but service selector is app=content-marlin-deployment (or vice versa), fix the Service selector to match pod labels.
Service should have:
spec:
selector:
app: <label-that-actually-exists-on-pods>
Fix pattern D: Service targetPort wrong
If container listens on 8080 but service targetPort is 80, fix it:
spec:
ports:
- port: 80
targetPort: 8080
5) Apply the corrected manifests
After editing the YAMLs under /home/candidate/content-marlin/:
kubectl apply -f /home/candidate/content-marlin/
Wait for readiness:
kubectl -n content-marlin rollout status deploy content-marlin-deployment kubectl -n content-marlin get endpoints kubectl -n content-marlin describe ingress content-marlin-ingress
6) Re-test the URL
curl -i -H "Host: content-marlin.local"
http://127.0.0.1/content-marlin
If you still get errors, also check ingress controller logs/events quickly:
kubectl -n content-marlin get events --sort-by=.lastTimestamp | tail -n 30 kubectl get pods -A | egrep -i 'ingress|nginx' The fastest way for you to finish in 1 shot Run these and paste the output (I'll tell you exactly which line to change and what to change it to):
kubectl -n content-marlin describe ingress content-marlin-ingress
kubectl -n content-marlin get svc -o wide
kubectl -n content-marlin get endpoints -o wide
kubectl -n content-marlin get pods --show-labels
sed -n '1,200p' /home/candidate/content-marlin/*.yaml
But even without pasting, if you follow steps 2-4 above, you'll find the broken link (Ingress rule, Service port, selector, or rewrite) and fix it cleanly.
NEW QUESTION # 84
You have a web application that uses two different services: 'frontend' and 'backend'. You want to restrict access to the 'backend' service from all pods except those with the label 'app: frontend'. How would you configure NetworkPolicy to achieve this?
Answer:
Explanation:
See the solution below with Step by Step Explanation.
Explanation: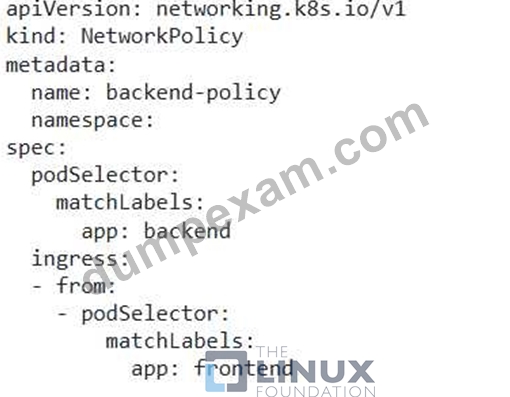
- Replace with your actual namespace. 2. Apply the NetworkPolicy: - Run the following command to apply the NetworkPolicy: bash kubectl apply -f backend-networkpolicy.yaml - This NetworkPolicy defines a policy for pods with the label 'app: backend'. - The 'ingress' rule allows traffic only from pods with the label 'app: frontend'. - All other pods will be blocked from accessing the 'backend' service. This ensures that only the frontend' service can communicate with the 'backend' service. ,
NEW QUESTION # 85
Context
Context
Your application's namespace requires a specific service account to be used.
Task
Update the app-a deployment in the production namespace to run as the restrictedservice service account. The service account has already been created.
Answer:
Explanation:
Solution: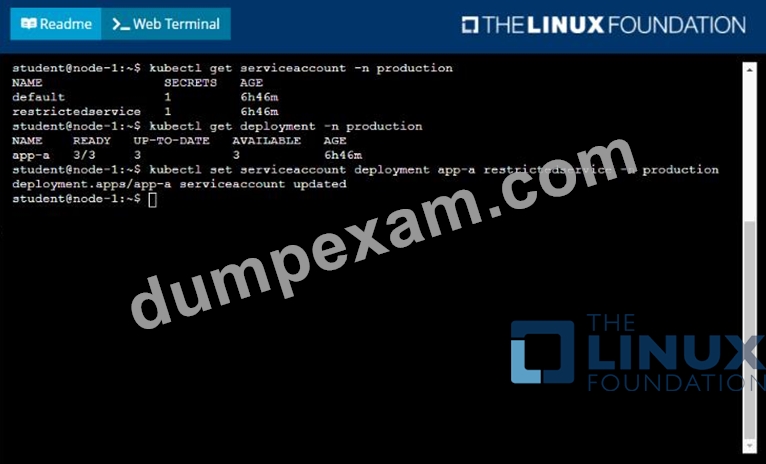
NEW QUESTION # 86
You nave a Deployment running a web application tnat uses secrets to store sensitive information like database credentials. To improve security, you want to use a secret injection mechanism to provide the secret to the pod without exposing it in the deployment YAML.
Answer:
Explanation:
See the solution below with Step by Step Explanation.
Explanation:
Solution (Step by Step) :
1. Create a Secret:
- Create a secret containing the sensitive information: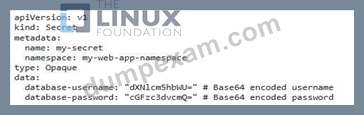
2. Configure Deployment to Use Secret: - Update the Deployment YAML to mount the secret into the container: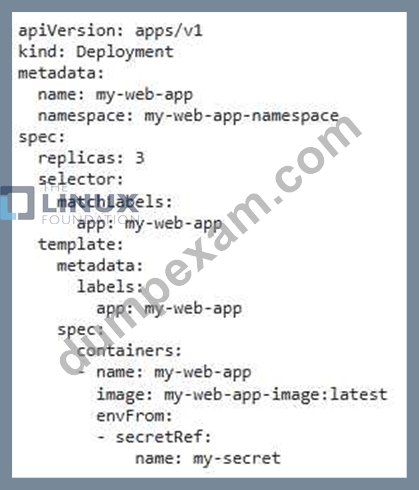
3. Apply the Configuration: - Apply tne Secret and Deployment configuration: bash kubectl apply -f my-secret.yaml kubectl apply -f my-web-app-deployment.yaml 4. Verify Secret Injection: - Access the secret information from within the container using environment variables: - For example, '$DATABASE_USERNAME and '$DATABASE PASSWORD'.
NEW QUESTION # 87
Context
Context
You have been tasked with scaling an existing deployment for availability, and creating a service to expose the deployment within your infrastructure.
Task
Start with the deployment named kdsn00101-deployment which has already been deployed to the namespace kdsn00101 . Edit it to:
* Add the func=webFrontEnd key/value label to the pod template metadata to identify the pod for the service definition
* Have 4 replicas
Next, create ana deploy in namespace kdsn00l01 a service that accomplishes the following:
* Exposes the service on TCP port 8080
* is mapped to me pods defined by the specification of kdsn00l01-deployment
* Is of type NodePort
* Has a name of cherry
Answer:
Explanation:
Solution:


NEW QUESTION # 88
You have a Kubernetes deployment tnat uses a ConfigMap to provide configuration settings to your application. You need to update tne ConfigMap with new settings without restarting the deployment.
Answer:
Explanation:
See the solution below with Step by Step Explanation.
Explanation:
Solution (Step by Step) :
1. Update the ConfigMap:
- Create or update your ConfigMap YAML file, for example, Sapp-config.yaml':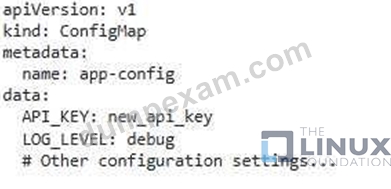
- Replace and 'debug' with the desired new values. 2. Apply the Updated ConfigMap: - Apply the updated ConfigMap using: bash kubectl apply -f app-config.yaml 3. Verify the Update: - Check the updated ConfigMap using: bash kubectl get configmap app-config -o yaml - Confirm that the new settings are reflected in the ConfigMap. 4. (Optional) Monitor Application Logs: - If your application is logging configuration values, you can check the logs to ensure it's now using the updated settings.
NEW QUESTION # 89
You are developing a new feature for your application that requires a new microservice to be deployed. This microservice interacts With a database, and you want to ensure the database connection is handled securely and efficiently. Design a deployment strategy for the new microservice that integrates with the database and implements security best practices.
Answer:
Explanation:
See the solution below with Step by Step Explanation.
Explanation:
Solution (Step by Step) :
1. Use a Deployment:
- Deploy your new microservice using a Deployment Deployments provide a robust mechanism for managing and scaling your microservices, making it easy to update and manage your application.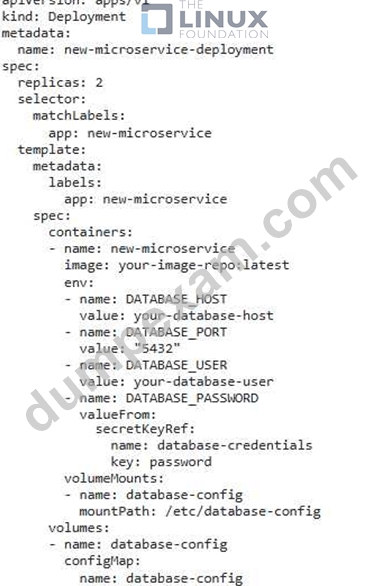
2. Secure Database Credentials: - Store database credentials in a Kubernetes Secret, which is encrypted at rest. This ensures that the credentials are not exposed in plain text in your deployments.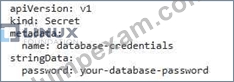
3. Configure Database Connection Details: - Define environment variables Within your Deployment to pass database connection details (like host, port, username, and password) to the container- 4. Use ConfigMaps for Configuration: - Utilize ConfigMaps to manage database connection settings (like connection strings or configuration files) that are common across multiple pods. This makes it easier to update configuration details without modifying your deployments directly.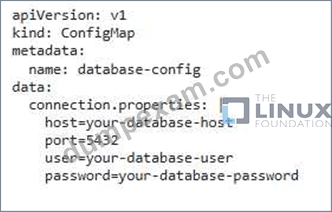
5. Implement Database Connection Pooling. - Use a database connection pool to manage connections efficiently, reducing the overhead of establishing and closing connections frequently. 6. Consider Using Database-as-a-Service (DBaaS): - If your application is running in a cloud environment, consider leveraging a DBaaS service like Amazon RDS, Google Cloud SQL, or Azure SQL Database. DBaaS services provide managed database infrastructure, simplifying database management, scaling, and security. T Implement Database Security Practices: - Configure database security measures like access control lists (ACLs), encryption at rest, and audit logging to ensure data security
NEW QUESTION # 90
You have a Deployment named 'redis-deployment that runs 3 replicas of a Redis container. You need to implement a rolling update strategy that allows tor a maximum ot one pod to be unavailable at any given time during tne update process, With the new pod becoming available before the old pod is terminated. Additionally, you want to ensure that the update process is triggered automatically whenever a new image is pushed to the Docker Hub repository 'redislabs/redis:latest.
Answer:
Explanation:
See the solution below with Step by Step Explanation.
Explanation:
Solution (Step by Step) :
1. Update the Deployment YAML:
- Update the 'replicas to 2_
- Define 'maxunavailable: 1 ' and 'maxSurge: 1 ' in the 'strategy.rollingupdate' section to control the rolling update process.
- Configure a 'strategy-type' to 'Rollingupdate' to trigger a rolling update when the deployment is updated.
- Add a 'spec-template.spec.imagePullPolicy: Always' to ensure that the new image is pulled even if it exists in the pod's local cache.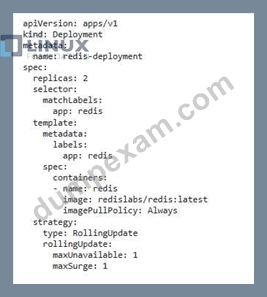
2. Create the Deployment: - Apply the updated YAML file using 'kubectl apply -f redis-deployment.yaml' 3. Verify the Deployment - Check the status of the deployment using 'kubectl get deployments redis-deployment' to confirm the rollout and updated replica count. 4. Trigger the Automatic Update. - Push a new image to the Docker Hub repository 5. Monitor the Deployment: - Use 'kubectl get pods -l app=rediS to monitor the pod updates during the rolling update process. You will observe that one new pod with the updated image is created, and then one old pod is terminated- This ensures that there is no downtime during the update process. 6. Check for Successful Update: - Once the deployment is complete, use 'kubectl describe deployment redis-deployment' to see that the 'updatedReplicaS field matches the 'replicas' field, indicating a successful update.
NEW QUESTION # 91 
Task:
Create a Pod named nginx resources in the existing pod resources namespace.
Specify a single container using nginx:stable image.
Specify a resource request of 300m cpus and 1G1 of memory for the Pod's container.
Answer:
Explanation:
See the solution below.
Explanation
Solution:
Text Description automatically generated with medium confidence
Text Description automatically generated
Text Description automatically generated
NEW QUESTION # 92 
Task
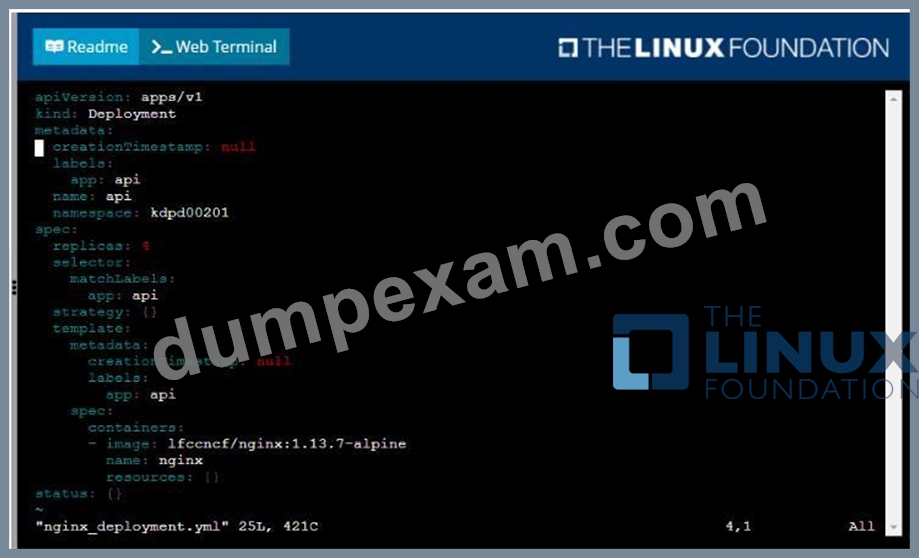
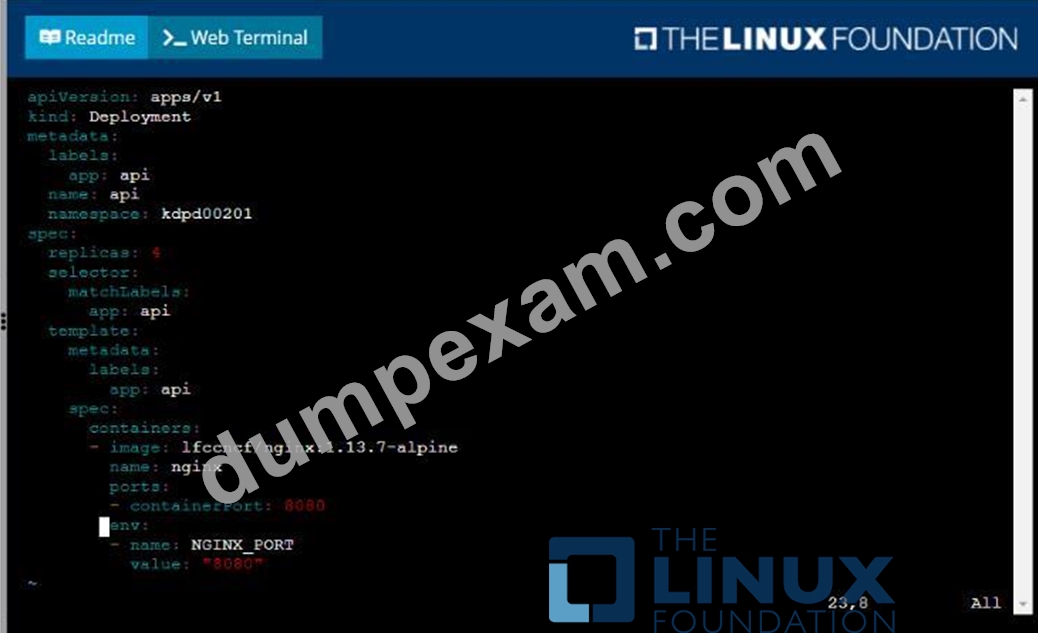
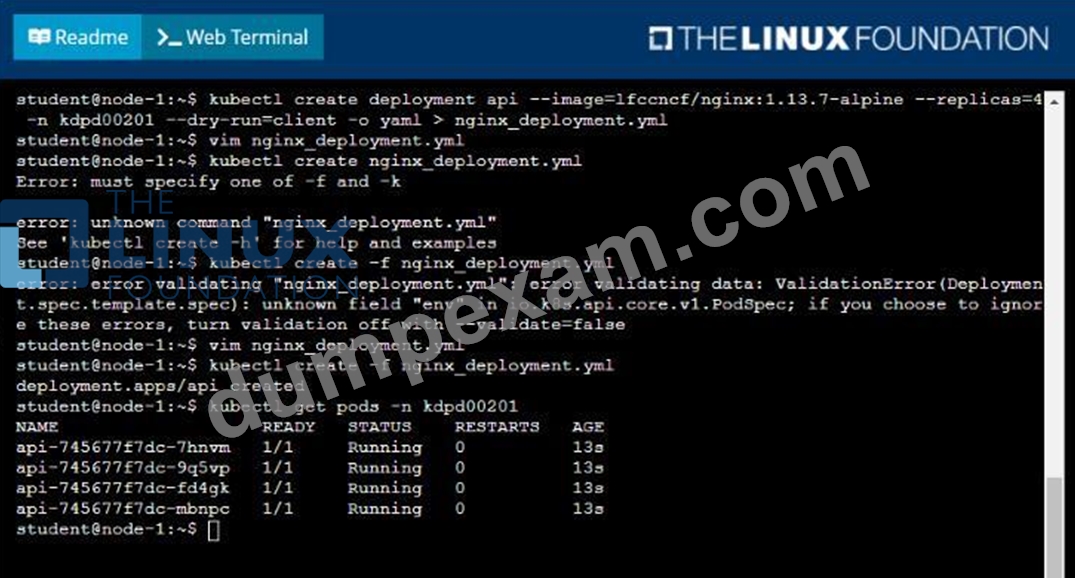
Create a new deployment for running.nginx with the following parameters;
* Run the deployment in the kdpd00201 namespace. The namespace has already been created
* Name the deployment frontend and configure with 4 replicas
* Configure the pod with a container image of lfccncf/nginx:1.13.7
* Set an environment variable of NGINX__PORT=8080 and also expose that port for the container above See the solution below.
Answer:
Explanation:
Explanation
Solution: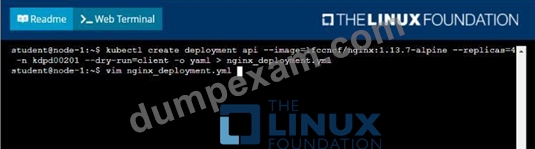
NEW QUESTION # 93
You are tasked with creating a highly available, scalable, and stateful application that handles user profiles and associated dat a. The application must be able to handle high write and read traffic and ensure data consistency. Which Kubernetes resource is best suited tor this scenario and why? Additionally, provide a code snippet illustrating the deployment of this resource with three replicas, each storing user data in a persistent volume.
Answer:
Explanation:
See the solution below with Step by Step Explanation.
Explanation:
Solution (Step by Step) :
1. Identify the Suitable Resource:
- The best Kubernetes resource for this scenario is a StatefulSet.
- StatefulSets provide unique network identities and persistent storage for each pod, making them ideal for stateful applications. They ensure ordered deployments and rollbacks, guaranteeing that pods are always launched in a specific order and with consistent data
2. Code Snippet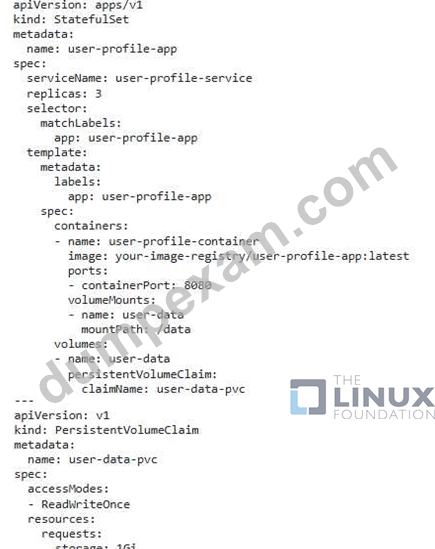
- StatefulSet Definition: Defines the StatefulSet With the name "user-profile-app", sets the replica count to 3, and defines a selector that matches pods with the label "app: user-profile-app". - Service Definition: Sets up a service named "user-profile-service" that exposes the application on port 8080. - Template: Defines tne pod template for each replica. - Container: Specifies the container image, port mapping, and volume mounting for the user datm - Volume Mounts: Mounts the persistent volume claim "user-data" to the ' Idata' directory inside the container. - Volumes: Defines tne persistent volume claim "user-data" which is linked to a PersistentVolumeClaim named "user-data-pvc." - PersistentVolumeClaim: Defines a PersistentVolumeClaim named "user-data-pvc" to request a persistent volume with 1 Gi storage- 4. Deployment Steps: - Create the PersistentVolumeClaim (PVC) using kubectl apply -f user-profile-app.yamr - Create the StatefulSet using 'kuactl apply -f user-profile-app.yaml' - Access the application through the service name "user-profile-service" This setup creates a highly available and scalable application that ensures data persistence and consistency across three replicas. ]
NEW QUESTION # 94
You have a Kubernetes cluster with a deployment named 'myapp'. This deployment utilizes a service account named 'my-sas to access a private registry. You need to grant this service account access to pull images from the registry, which requires an image pull secret named 'my-secret How would you configure the service account to use this image pull secret and ensure your myapp' deployment can successfully pull images?
Answer:
Explanation:
See the solution below with Step by Step Explanation.
Explanation:
Solution (Step by Step) :
1. Create a Service Account:
- If you haven't already, create a service account named 'my-sa':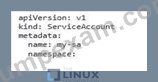
- Apply this YAML file using 'kubectl apply -f my-sa.yaml. 2. Create an Image Pull Secret: - Create a secret containing the necessary credentials for your private registry: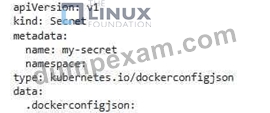
- Replace with the base64 encoded contents of your Docker configuration file. You can obtain this by using 'cat ~/.docker/config.json | base64'. - Apply the YAML file using 'kubectl apply -f my-secret.yaml' 3. Associate the Secret with the Service Account: - Add the 'my-secret' secret to tne 'my-sa' service account: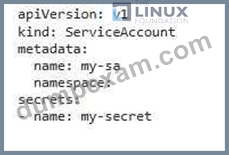
- Apply this YAML file using ' kubectl apply -f my-sa_yamr 4. Update Deployment with Service Account - Update the deployment configuration for 'myapp' to use the 'my-sa' service account.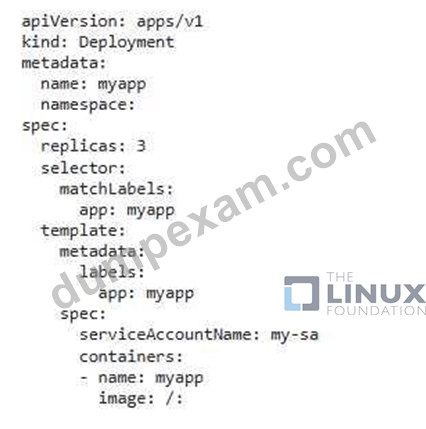
- Ensure that 'your-private-registry', 'your-image', and 'your-tag' match the details of your private registry image. - Apply the updated deployment configuration using 'kubectl apply -f myapp.yamr 5. Verify Deployment: - Check the status of the deployment using ' kubectl get deployments myapp'. You should see the pods successfully pulling images from your private registry Important Notes: - Security Best Practices: Always use dedicated service accounts with minimal permissions. - Image Pull Secret: The 'my-secret' secret should be securely stored and managed. - Namespace: Ensure that both the service account and secret are in the same namespace as your deployment. - Registry Authentication: Ensure your private registry is configured with proper authentication for your service account credentials.,
NEW QUESTION # 95 
Task:
Update the Pod ckad00018-newpod in the ckad00018 namespace to use a NetworkPolicy allowing the Pod to send and receive traffic only to and from the pods web and db
Answer:
Explanation:
See the solution below.
Explanation:
Solution:
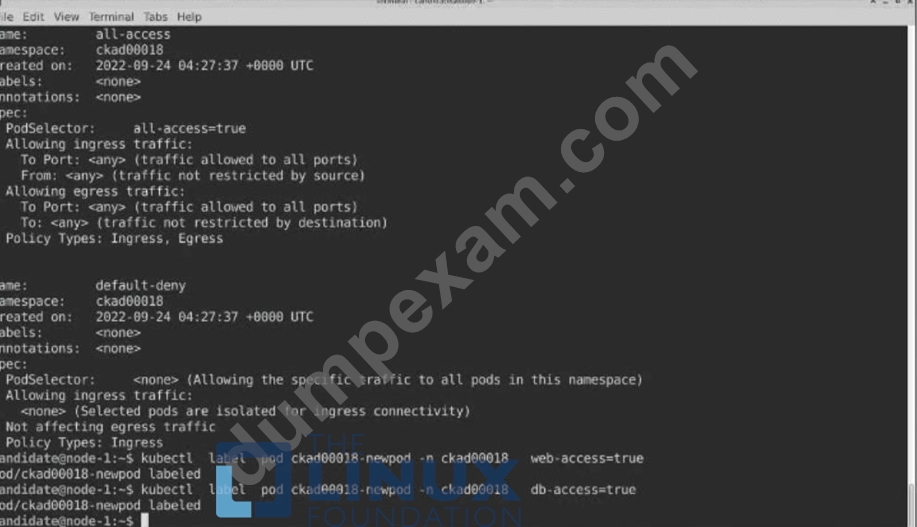
NEW QUESTION # 96
Context
You are asked to deploy an application developed for an older version of Kubernetes on a cluster running a recent version of Kubernetes .
You must connect to the correct host . Failure to do so may result in a zero score.
[candidate@base] $ ssh ckad00026
Task
Fix any API -deprecation issues in the manitest file
/home/candidate/credible-mite/web.yaml
so that the application can be deployed on cluster ckad00026.
The application was developed for Kubernetes v1.15.
The cluster ckad00026 runs Kubernetes 1.29+.
Deploy the application specified in the updated manifest file
/home/candidate/credible-mite/web.yaml in namespace garfish .
Answer:
Explanation:
See the Explanation below for complete solution.
Explanation:
ssh ckad00026
Your job is to edit /home/candidate/credible-mite/web.yaml so it uses APIs supported on Kubernetes 1.29+, then deploy it into namespace garfish.
Because I can't see your file from here, the most reliable exam approach is:
* run a server-side dry-run to reveal the exact deprecated/removed APIs and schema errors
* edit the manifest to the modern API versions/fields
* re-run dry-run until it passes
* apply for real and verify rollout
1) Go to the manifest and run a server-side dry-run
cd /home/candidate/credible-mite
ls -l
sed -n '1,200p' web.yaml
Make sure the namespace exists:
kubectl get ns garfish || kubectl create ns garfish
Now run a server-side dry-run (this catches removed APIs on the cluster):
kubectl apply -n garfish -f web.yaml --dry-run=server
Whatever errors you get here tell you exactly what to fix.
2) Fix the common v1.15 # v1.29 API deprecations
Edit the file:
vi web.yaml
Below are the most common objects from older manifests and how to update them for 1.29+.
A) Deployments / DaemonSets / StatefulSets
Old (v1.15 often used):
* extensions/v1beta1 or apps/v1beta1 or apps/v1beta2
New:
* apiVersion: apps/v1
Also in apps/v1, .spec.selector is required and must match the pod template labels.
Example conversion:
apiVersion: apps/v1
kind: Deployment
metadata:
name: web
spec:
replicas: 2
selector:
matchLabels:
app: web
template:
metadata:
labels:
app: web
spec:
containers:
- name: web
image: nginx
Key rule:
spec.selector.matchLabels must exactly match spec.template.metadata.labels (at least for the keys you select on).
B) Ingress
Old:
* apiVersion: extensions/v1beta1 (or networking.k8s.io/v1beta1)
New:
* apiVersion: networking.k8s.io/v1
Required changes:
* spec.rules.http.paths[].pathType is required (usually Prefix)
* backend format changes from serviceName/servicePort to service.name/service.port.number (or .name for named ports) Old backend:
backend:
serviceName: web
servicePort: 80
New backend:
backend:
service:
name: web
port:
number: 80
Full path example:
apiVersion: networking.k8s.io/v1
kind: Ingress
metadata:
name: web
spec:
rules:
- host: example.local
http:
paths:
- path: /
pathType: Prefix
backend:
service:
name: web
port:
number: 80
C) CronJob
Old:
* apiVersion: batch/v1beta1
New:
* apiVersion: batch/v1
Most fields stay the same; just update apiVersion.
D) PodDisruptionBudget
Old:
* policy/v1beta1
New:
* policy/v1
spec.selector/minAvailable/maxUnavailable remain, but apiVersion changes.
E) RBAC
Usually already:
* rbac.authorization.k8s.io/v1 (this is fine)
F) Removed APIs you must delete/replace
If you see these in a v1.15-era manifest, they are removed in modern clusters:
* PodSecurityPolicy (policy/v1beta1) is removed. You cannot deploy it on 1.29+. Remove it from the manifest (or replace with whatever your environment uses, but for CKAD tasks you usually delete PSP sections from the file).
* Some old admission/alpha resources also removed.
If dry-run complains "no matches for kind ... in version ...", that's your cue.
3) Re-run dry-run until it succeeds
After you edit:
kubectl apply -n garfish -f web.yaml --dry-run=server
Keep iterating until there are no errors.
4) Deploy for real
kubectl apply -n garfish -f /home/candidate/credible-mite/web.yaml
5) Verify everything in namespace garfish
List what was created:
kubectl -n garfish get all
kubectl -n garfish get ingress 2>/dev/null || true
If there is a Deployment, verify rollout:
kubectl -n garfish get deploy
kubectl -n garfish rollout status deploy --all
Check pods/events if something fails:
kubectl -n garfish get pods -o wide
kubectl -n garfish describe pod <pod-name>
kubectl -n garfish get events --sort-by=.lastTimestamp | tail -n 30
NEW QUESTION # 97
You're building a microservice architecture that uses a load balancer to distribute traffic across multiple instances of a service. You want to implement a health check mechanism that ensures only healthy instances receive traffic. Design a solution using Kubernetes Liveness probes and a service With a health check configuration.
Answer:
Explanation:
See the solution below with Step by Step Explanation.
Explanation:
Solution (Step by Step) :
1. Define a Liveness Probe in the Deployment: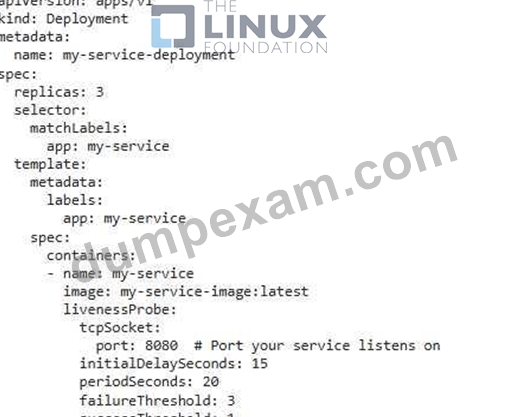
- Replace 'my-service-image:latest' with your service image. - Replace '8080' with the port your service listens on. - Adjust the probe settings as needed. 2. Create a Service with Health Check Configuration: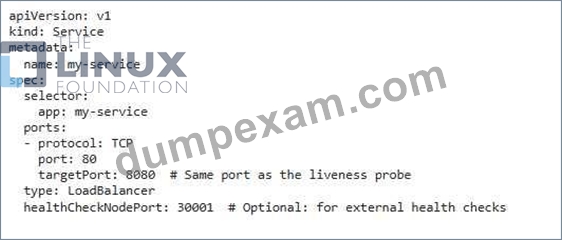
- 'healthCheckNodePort' is optional, but can be used for external health checks against the service. 3. Apply the YAML Files: - Apply the Deployment and Service using 'kubectl apply -f deployment_yamr and ' kubectl apply -f service.yaml'. 4. Verify the Health Checks: - Check the service logs for liveness probe results. - If a pod becomes unhealthy, it should be restarted by the liveness probe. - You can also use 'kubectl get pods -I app=my-service' to check the pod status. 5. Advanced Configuration: - Use 'exec' or 'httpGet' probes for more complex health check requirements. - Configure the 'failureThreshold' and "successThreshold' to adjust the probe's sensitivity. - Add a 'readinessProbe' to the Deployment for readiness checks that determine when a pod is ready to receive traffic. ,
NEW QUESTION # 98
You have a microservice application that consists of two components: a web server (using Nginx) and a database (using PostgreSQL). The web server needs to access the database through a local connection, but due to network security restrictions, the web server cannot connect to the database directly. Describe how you can utilize a sidecar container to resolve this issue and ensure the database connection is secure.
Answer:
Explanation:
See the solution below with Step by Step Explanation.
Explanation:
Solution (Step by Step) :
1. Create a Sidecar Container:
- Define a new container in your Deployment's 'spec-template-spec-containers' array, alongside the existing Nginx container. This new container will house the necessary tools for facilitating a secure database connection.
- Name this container appropriately, for example, 'database-proxy'
- Choose an image that contains the required software for database connection, such as 'postgres' or 'postgresqr
- Use a sidecar pattern in the Deployment YAML file. You can specify the sidecar in the container array in the Pod specification: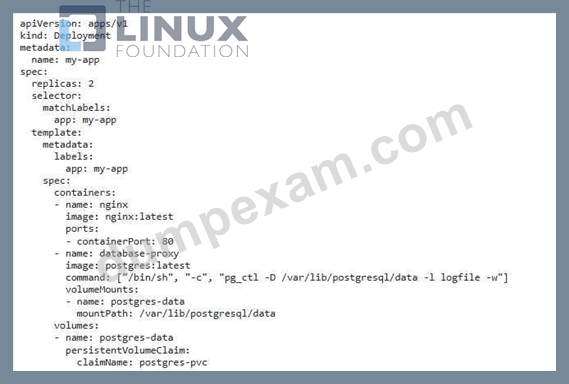
2. Database Connection Configuration: - Configure the sidecar container to connect to the database. - Establish a connection using the database user credentials and connection string. - If you use a secure connection, ensure that the certificates and private keys are accessible to the sidecar container. 3. Communication Between Containers: - Configure your web server container to communicate with the sidecar container. - Use environment variables to specify the hostname and port of the sidecar container, enabling the web server to connect to the database proxy within the pod. 4. Volume Sharing: - Optionally, share a volume between the web server and the sidecar container to facilitate shared data access, such as database configuration files. 5. Deploy the Deployment: - Apply the updated Deployment YAML file to your Kubernetes cluster using 'kubectl apply -f my-app.yaml' 6. Test the Application: - Access your web server application and confirm that it successfully connects to the database through the sidecar container.
NEW QUESTION # 99
You have a Kubernetes deployment tnat uses a ConfigMap to provide configuration settings to your application. You need to update tne ConfigMap with new settings without restarting the deployment.
Answer:
Explanation:
See the solution below with Step by Step Explanation.
Explanation:
Solution (Step by Step) :
1. Update the ConfigMap:
- Create or update your ConfigMap YAML file, for example, Sapp-config.yaml':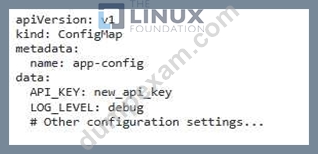
- Replace and 'debug' with the desired new values. 2. Apply the Updated ConfigMap: - Apply the updated ConfigMap using: bash kubectl apply -f app-config.yaml 3. Verify the Update: - Check the updated ConfigMap using: bash kubectl get configmap app-config -o yaml - Confirm that the new settings are reflected in the ConfigMap. 4. (Optional) Monitor Application Logs: - If your application is logging configuration values, you can check the logs to ensure it's now using the updated settings.
NEW QUESTION # 100
......
The CKAD exam consists of a set of performance-based tasks that must be completed within a three-hour time frame. The tasks are designed to simulate real-world scenarios that developers may encounter when working with Kubernetes. CKAD exam covers a wide range of topics, including Kubernetes architecture, deployment, configuration, troubleshooting, and security. Candidates must demonstrate a deep understanding of these topics and be able to apply their knowledge to solve complex problems.
The CKAD exam is designed for developers who are already proficient in Kubernetes application development and want to validate their skills. CKAD exam tests candidates on a variety of topics including core concepts, configuration, multi-container pods, observability, pod design, services and networking, state persistence, and troubleshooting. CKAD exam is based on the Kubernetes v1.19 curriculum, which is the latest version of Kubernetes at the time of writing.
100% Free CKAD Daily Practice Exam With 239 Questions: https://www.dumpexam.com/CKAD-valid-torrent.html
Pass CKAD Review Guide, Reliable CKAD Test Engine: https://drive.google.com/open?id=1q0x9-prKekA_0IF6LiWYcmHpytVSr4b_
